Hera User Guide
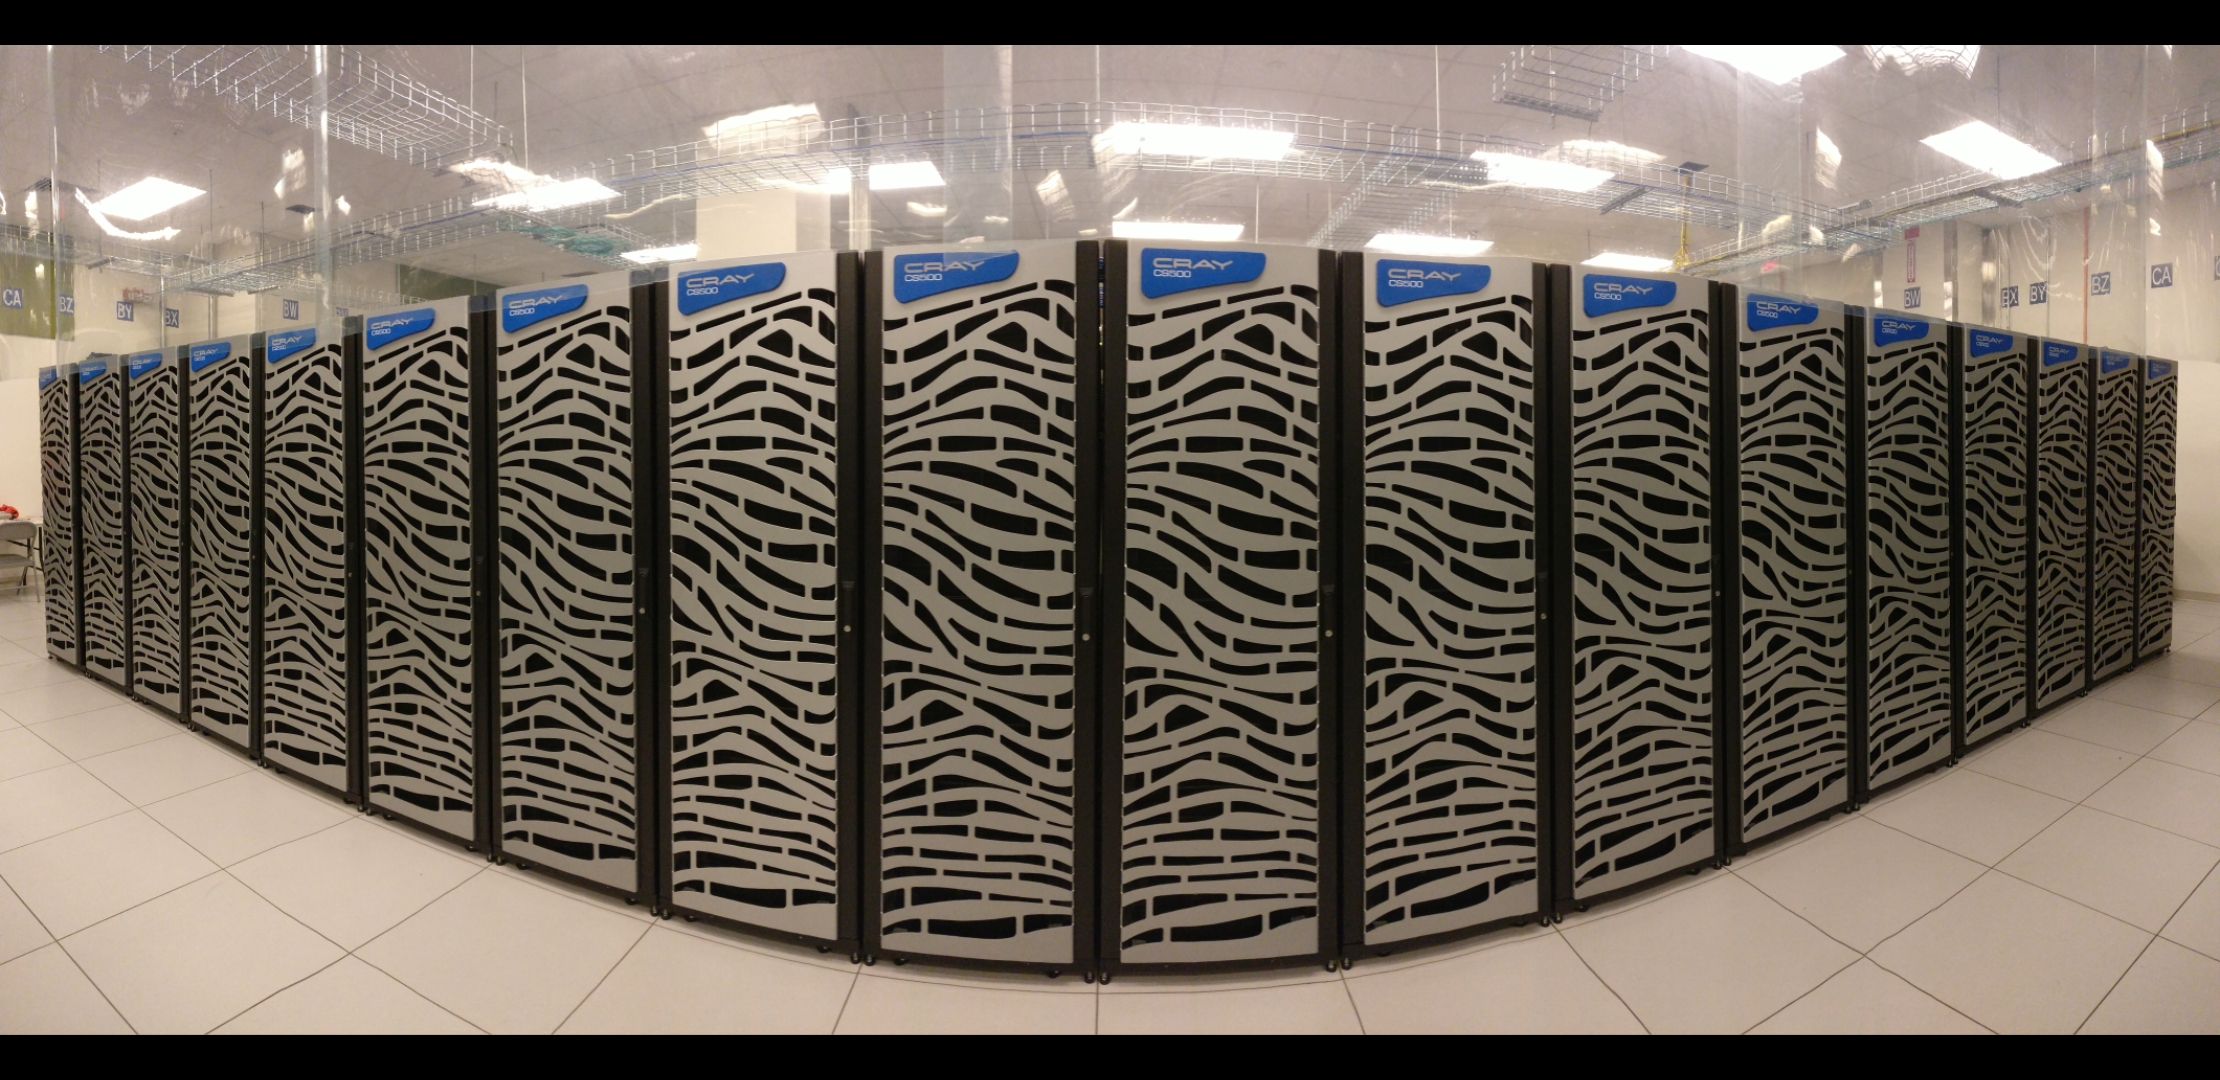
System Overview
Capacity of 3,270 trillion floating point operations per second – or 3.27 petaFLOPS
45 million hours per month with 63,840 cores and a total scratch disk capacity of 9.1 Petabytes.
NESCC is also home to Niagara, a cloud-based computing resource. In addition, Test and Development systems are available through NESCC for system and application testing.
System Configuration
Hera |
|
|---|---|
CPU Type |
Intel SkyLake |
CPU Speed (GHz) |
2.40 |
Reg Compute Nodes |
1,328 |
Cores/Node |
40 |
Total Cores |
63,840 |
Memory/Core (GB)/Node |
96 |
Peak FLOPS/Node |
12 |
Service Code Memory (GB) |
187 |
Total BigMem Nodes |
268 |
BigMem Node Memory (GB) |
384 |
CPU FLOPS (TFLOPS) |
2,672 |
Interconnect |
HDR-100 IB |
Note
The Skylake 6148 CPU has two AVX-512 units and hence a theoretical peak of 32 double precision floating point operations per cycle with a base clock rate for floating point operations of 1.6 GHz.
Total FLOPS is a measure of peak, and doesn’t necessarily represent actual performance.
Juno is the Test and Development System. Users must be granted specific access to the system for use.
Hera Partitions
To specify a partition, use the command partition -p. For example:
sbatch -p batch ...
The following partitions are defined for Hera:
Partition |
QOS Allowed |
Billable TRes per Core Performance Factor |
Description |
|---|---|---|---|
hera |
batch,windfall, debug, urgent, long |
165 |
General compute resource. Default if no partition is specified |
bigmem |
batch,windfall, debug, urgent, long |
165 |
For large memory jobs; 268 nodes, each with 40 cores and 384 GB of memory |
novel |
novel |
165 |
Partition to run novel or experimental jobs where nearly the full system is required. If you need to run a novel job, please submit a help ticket and tell us what you want to do. We will normally have to arrange for some time for the job to go through, and we would like to plan the process with you. Also, please note that if you use novel partition you also need to specify novel QoS. |
service |
batch,windfall |
165 |
For jobs that require external network connectivity (including access to the HPSS archival system). Default of 1 core with a maximum of 4 cores and a maximum time limit of 24 hrs. Jobs will be run on front end nodes as those have external network connectivity. Useful for data transfers or access to external resources like databases. If your workflow requires pushing or pulling data to/from the HSMS(HPSS), it should be run there. See the Login (Front End) Node Usage Policy for important information about using Login nodes. |
To see a list of available partitions use the command
$ sinfo -O partition
hera*
service
bigmem
novel
An asterisk (*) indicates that default partition, where your job will be submitted to if you do not specify a partition name at job submission.
General compute jobs: To assure the systems are used most efficiently, specify the use of all general compute resource partitions. This allows the batch scheduler to put your jobs on the first available resource.
File System Usage
Hera file systems are shared with Ursa. For information on the shared file systems available for Hera, see the High Performance File System section of the Ursa User Guide.
Applications and Libraries
A number of applications are available on Hera. They should be run on a compute node. They are serial tasks, not parallel, and thus, a single core may be sufficient. If your memory demands are large, it may be appropriate to use an entire node even though you are using only a single core.
Using Miniforge3 and Python on Hera
See Installing Miniforge for installation instructions.
Warning
RDHPCS support staff does not have the available resources to support or maintain these packages. You will be responsible for the installation and troubleshooting of the packages you choose to install. Due to architectural and software differences some of the functionality in these packages may not work.
MATLAB
Information is available TBD
Using IDL on Hera
The IDL task can require considerable resources. It should not be run
on a frontend node. It is recommended that you run IDL on a compute
node either in a job or via interactive job. Take a whole node and
there is no need to use the --mem=<memory> parameter. If you
request a single task you would get a shared node and in those
instances you should consider using --mem=<memory> option (since
IDL is memory intensive).
To run IDL on an interactive queue:
$ salloc -x11=first -ntasks=40 -t 60 -A <account>
$ cd <your working directory>
$ module load idl
$ idl      # or idled
IDL can be run from a normal batch job as well.
Multi-Threading in IDL
IDL is a multi-threaded program. By default, the number of threads is set to the number of CPUs present in the underlying hardware. The default number of threads for Hera compute nodes is 48 (the number of virtual CPUs). It should not be run as a serial job with the default thread number, as the threaded program will affect other jobs on the same node.
The number of threads needs to be set to 1 if a job is going to be
submitted as a serial job, which can be achieved by setting the
environment variable IDL_CPU_TPOOL_NTHREADS to 1, or setting it
with the CPU procedure in IDL: CPU, TPOOL_NTHREADS = 1. If a job
requires larger than 10 GB memory, you should run the job on
either the bigmem node or a whole node.
Using ImageMagick on Hera
The ImageMagick module can be loaded on Hera with the following command:
$ module load imagemagick
The modules set an environment variable and paths in your environment to access the files.
- $MAGICK_HOME:
is set to the base directory
- $MAGICK_HOME/bin:
is added to your search path
- $MAGICK_HOME/man:
is added to your MANPATH
- $MAGICK_HOME/lib:
is added to your LD_LIBRARY_PATH
ImageMagick, and the utilities that are part of this package
including convert, should be run on a compute node for
gang processing of many files, either via a normal batch job
or via an interactive job.
Using R on Hera
R is a software environment for statistical computing and graphics. It is available on Hera as a module within the Intel module families. The R module can be loaded on Hera with the following commands:
$ module load intel
$ module load R
R has many contributed packages that can be added to standard R. CRAN, the global repository of open-source packages that extend the capabilities of R, has a complete list of R packages as well as the packages for download.
Due to access restrictions from Hera to the CRAN repository, you may need to download an R package to your local workstation first, then copy it to your space on Hera to install the package as detailed below.
To install a package from the command line:
$ R CMD INSTALL <path_to_file>
To install a package from within R
> install.packages("path_to_file", repos = NULL, type="source")
where path_to_file would represent the full path and file name.
When you try to install a package for the first time, you may get a message similar to:
'lib = "/apps/R/3.2.0-intel-mkl/lib64/R/library"' is not writable
Would you like to use a personal library instead?  (y/n)
Reply with y and it will prompt you for a location.
Libraries
A number of libraries are available on Hera. The following command can be used to list all the available libraries and utilities:
module spider
Using Modules
Hera uses the LMOD hierarchical modules system. LMOD is a Lua based
module system that makes it easy to place modules in a hierarchical
arrangement. So you may not see all the available modules when you
type the module avail command.
See Modules
Using MPI
Loading the MPI module
There are two MPI implementations available on Hera: Intel MPI and MVAPICH2. We recommend one of the following two combinations:
IntelMPI with the Intel compiler
MVAPICH2 with the PGI compiler.
At least one of the MPI modules must be loaded before compiling and running MPI applications. These modules must be loaded before compiling applications as well in your batch jobs before executing a parallel job.
Working with Intel Compilers and IntelMPI
At least one of the MPI modules must be loaded before compiling and running MPI applications. This is done as follows:
$ module load intel impi
Compiling and Linking MPI applications with IntelMPI
For the primary MPI library, IntelMPI, the easiest way to compile applications is to use the appropriate wrappers: mpiifort, mpiicc, and mpiicpc.
$ mpiifort -o hellof hellof.f90
$ mpiicc -o helloc helloc.c
$ mpiicp -o hellocpp hellocpp.cpp
Note
Please note the extra “i” in mpiifort. mpiicc, and
mpiicp commands.
Launching MPI applications with IntelMPI
For instructions on how to run MPI applications please refer to Running and Monitoring Jobs.
Launching an MPMD application with intel-mpi-library-documentation
For instructions on how to run MPI applications please refer to Running and Monitoring Jobs.
Launching OpenMP/MPI hybrid jobs with IntelMPI
For instructions on how to run MPI applications please refer to Running and Monitoring Jobs.
Note about MPI-IO and Intel MPI
Intel MPI doesn’t detect the underlying file system by default when using MPI-IO. You have to pass the following variables on to your application:
export I_MPI_EXTRA_FILESYSTEM=on
export I_MPI_EXTRA_FILESYSTEM_LIST=lustre
Additional documentation on Intel MPI
The Intel documentation library has extensive documentation, the following are a list of specific documents that may be useful.
Intel PSM documentation. is very helpful for troubleshooting and turning purposes. This is because Intel MPI is based on the PSM layer.
Using PGI and mvapich2
At least one of the MPI modules must be loaded before compiling and running MPI applications. This is done with as follows:
module load pgi mvapich2
Compiling and Linking MPI applications with PGI and MVAPICH2
When compiling with the PGI compilers, please use the wrappers:
mpif90, mpif77, mpicc, and mpicpp.
$ mpif90 -o hellof hellof.f90
$ mpicc -o helloc helloc.c
$ mpicpp -o hellocpp hellocpp.cpp
Launching MPI applications with MVAPICH2
For instructions on how to run MPI applications please refer to Running and Monitoring Jobs.
Launching OpenMP/MPI hybrid jobs with MVAPICH2 (TBD)
For instructions on how to run MPI applications please refer to Running and Monitoring Jobs.
Additional documentation on using MVAPICH2
See the MVAPICH User Guide.
Tuning MPI (TBD)
Several options can be used to improve the performance of MPI jobs.
Profiling an MPI application with Intel MPI
Add the following variables to get profiling information from your runs:
export I_MPI_STATS=<num>      # Can choose a value up to 10
export I_MPI_STATS_SCOPE=col  # Statistics for collectives only
setenv I_MPI_STATS <num>      # Can choose a value up to 10
setenv I_MPI_STATS_SCOPE col  # Statistics for collectives only
The Intel runtime library has the ability to bind OpenMP threads to
physical processing units. The interface is controlled using the
KMP_AFFINITY environment variable. Thread affinity can have a dramatic
effect on the application speed. It is recommended to set
KMP_AFFINITY=scatter to achieve optimal performance for most
OpenMP applications. For details, review the information in the Intel
documentation library.
Intel Trace Analyzer
Intel Trace Analyzer (formerly known as Vampir Trace) can be used for analyzing and troubleshooting MPI programs. Please refer to the documentation. Even though we have modules created for “itac” for this utility, it may better to follow the instructions from the link above as the instructions for more recent versions may be different than when we created the module.
Debugging Codes
Debugging Intel MPI Applications
When troubleshooting MPI applications using Intel MPI, it may be helpful if the debug versions of the Intel MPI library are used. To do this, use one of the following:
$ mpiifort -O0 -g -traceback -check all -fpe0 -link_mpi=dbg ...             # if you are running non-multithreaded application
$ mpiifort -O0 -g -traceback -check all -fpe0 -link_mpi=dbg_mt -openmp ...  # if you are running multi-threaded application
Using the -link_mpi=dbg makes the wrappers use the debug versions
of the MPI library, which may be helpful in getting additional
traceback information.
In addition to compiling with the options mentioned above, you may be able to get some additional trace back information and core files if you change the core file size to be unlimited (the default value for core file is zero; hence call filed generation is disabled). In order to enable it you need to have the following in your shell initialization files in your home directory (the file name and the syntax depends on your login shell):
ulimit -c unlimited
limit coredumpsize unlimited
Application Debuggers
A GUI based debugger named DDT by Linaro is available on Hera. Linaro has detailed documentation.
Note
Since DDT is GUI debugger, interactions over a wide area network can be extremely slow.
Invoking DDT on Hera with Intel IMPI
Getting access to the compute resources for interactive use
For debugging you will need interactive access to the desired set of compute nodes using salloc with the desired set of resources:
$ salloc --x11=first -N 2 --ntasks=4 -A <project> -t 300 -q batch
At this point you are on a compute node.
Load the desired modules
$ module load intel impi forge
The following is a temporary workaround that is currently needed until it is fixed by the vendor.
$ export ALLINEA_DEBUG_SRUN_ARGS "%jobid% --gres=none --mem-per-cpu=0 -I -W0 --cpu-bind=none"
$ setenv ALLINEA_DEBUG_SRUN_ARGS "%jobid% --gres=none --mem-per-cpu=0 -I -W0 --cpu-bind=none"
Launch the application with the debugger
% ddt srun -n 4 ./hello_mpi_c-intel-impi-debug
This will open GUI in which you can do your debugging. Please note that by default it seems to save your current state (breakpoints, etc. are saved for your next debugging session).
Using DDT
Some things should be intuitive, but we recommend you look through the vendor documentation links shown above if you have questions.
Profiling Codes
Linaro Forge
Linaro Forge allows easy profiling of applications. Very brief instructions are included below.
Compile with the debug flag
Do not move your source files; the path is hardwired and will not found if relocated
Load the forge module with
module load forgeRun by prefixing with
map --profilebefore the launch command
#SBATCH ...
#SBATCH ...

module load intel impi forge

map --profile mpirun -np 8 ./myexe
Then submit the job as you normally do. Once the job has completed,
you should file *.map files in your directory.
You have to view those files using the allinea map
utility:
module load forge         # If not already loaded
map <map_file>.map
The above command will bring up a graphical viewer to view your profile
Perf-report is another tool that provides the profiling capability.
perf-report srun ./a.out
TAU
The TAU Performance System® is a portable profiling and tracing toolkit for performance analysis of parallel programs written in Fortran, C, C++, Java, and Python. It supports application use of MPI and/or OpenMP, and also supports GPU. Portions of the TAU toolkit are used to instrument code at compile time. Environment variables control a number of things at runtime. A number of controls exist, permitting users to:
specify which routines to instrument or to exclude
specify loop level instrumentation
instrument MPI and/or OpenMP usage
throttle controls to limit overhead impact of small, high frequency called routines
generate event traces
perform memory usage monitoring
The toolkit includes the Paraprof visualizer (a Java app) permitting use on most desk and laptop systems (Linux, MacOS, Windows) to view instrumentation data. The 3D display can be very useful. Paraprof supports the creation of user defined metrics based on the metrics directly collected (ex: FLOPS/CYCLE).
The event traces can be displayed with the Vampir, Paraver, or JumpShot tools.
Quick-start Guide for TAU
The Quick-start Guide for TAU only addresses basic usage. Please keep in mind that this is an evolving document!
Find the Quick Start TBD
Tutorial slides for TAU
A set of slides presenting a recipe approach to beginning with Tau is available TBD
MPI and OpenMP support
TAU build supports profiling of both MPI and OpenMP applications.
The Quick-start Guide mentions using
Makefile.tau-icpc-papi-mpi-pdt. This supports profiling of MPI
applications. You must use
Makefile.tau-icpc-papi-mpi-pdt-openmp-opari for OpenMP profiling.
Makefile.tau-icpc-papi-mpi-pdt-openmp-opari can be used for either
MPI or OpenMP or both.
Managing Contrib Projects
A /contrib package is one that is maintained by a user on the system. The system staff are not responsible for the use or maintenance of these packages. See Contrib for details.